<?xml version="1.0" encoding="utf-8"?><feed xmlns="http://www.w3.org/2005/Atom" ><generator uri="https://jekyllrb.com/" version="4.4.1">Jekyll</generator><link href="https://blog.farre.se/feed.xml" rel="self" type="application/atom+xml" /><link href="https://blog.farre.se/" rel="alternate" type="text/html" /><updated>2026-08-17T11:22:12+00:00</updated><id>https://blog.farre.se/feed.xml</id><title type="html">farre’s blog</title><subtitle>Blog by Andreas Farre</subtitle><author><name>Andreas Farre</name></author><entry><title type="html">Tracing algorithms through web specifications</title><link href="https://blog.farre.se/posts/2026/08/17/tracing-web-specs/" rel="alternate" type="text/html" title="Tracing algorithms through web specifications" /><published>2026-08-17T00:00:00+00:00</published><updated>2026-08-17T00:00:00+00:00</updated><id>https://blog.farre.se/posts/2026/08/17/tracing-web-specs</id><content type="html" xml:base="https://blog.farre.se/posts/2026/08/17/tracing-web-specs/"><![CDATA[<p>A bug comes in, or someone shows me a page doing something surprising, and the question is always the same one. Is that what the spec says? Not what we all assume it says, and not what Gecko happens to do, but what the algorithm actually does when you follow it step by step. So I open <a href="https://html.spec.whatwg.org/">html.spec.whatwg.org</a>, find the entry point, and start reading. Twenty tabs later I have usually lost the thread.</p>

<!-- more -->

<p>This isn’t an occasional chore. I do it when I’m implementing something new, when I’m working out whether a Gecko bug is a bug in Gecko or a bug in the spec, when I’m reviewing a spec change someone else has proposed, and when I’m trying to design something that has to fit alongside everything that already exists. Four fairly different jobs, and every one of them comes down to the same mechanical work. Start at an algorithm, follow the calls, keep track of where you’ve been.</p>

<p>The specs are built for exactly this, in principle. Every step that invokes another algorithm is a hyperlink, and the whole thing is one large call graph spread across HTML, DOM, Fetch, URL and Infra. The trouble is that walking that graph by hand is slow, and it’s the kind of slow a machine should be doing on your behalf.</p>

<p>Two tools have changed how I do this. One answers questions about the graph, and the other helps me walk it. If you’d rather install them first and read afterwards, <a href="#getting-them">they’re both at the end</a>.</p>

<h2 id="webspec-index-trace">webspec-index trace</h2>

<p><a href="https://github.com/jnjaeschke/webspec-index">webspec-index</a> is <a href="https://github.com/jnjaeschke/">Jan Jaeschke</a>’s tool for querying web specifications from the command line. It indexes the specs, on demand as it needs them, and lets you ask about definitions, references and IDL. In August it gained a <code class="language-plaintext highlighter-rouge">trace</code> subcommand, and that’s the one I keep reaching for.</p>

<p>You give it two anchors and it finds the routes between them. It answers in JSON by default, which is the right choice for feeding it into something else but not for reading, so add <code class="language-plaintext highlighter-rouge">--format markdown</code> when the audience is you. Say I want to know how a navigation can end up firing <code class="language-plaintext highlighter-rouge">navigateerror</code>:</p>

<figure class="highlight"><pre><code class="language-console" data-lang="console"><span class="gp">$</span><span class="w"> </span>webspec-index trace HTML#navigate HTML#event-navigateerror <span class="se">\</span>
<span class="go">    --format markdown</span></code></pre></figure>

<figure class="highlight"><pre><code class="language-text" data-lang="text"># trace: `HTML#navigate` -&gt; `HTML#event-navigateerror`

Max depth 6, kind `step`. Found 11 trace(s).

## Trace 1 (5 hop(s))

1) [`HTML#navigate` step 20](…#beginning-navigation:set-the-ongoing-navigation)
   calls `HTML#set-the-ongoing-navigation`
   &gt; Set the ongoing navigation for navigable to navigationId.

2) [`HTML#set-the-ongoing-navigation` step 2](…#aborting-navigation:inform-the-…)
   calls `HTML#inform-the-navigation-api-about-aborting-navigation`
   &gt; Inform the navigation API about aborting navigation given navigable.

3) [`HTML#inform-the-navigation-api-…` step 3.1](…#ongoing-navigation-tracking:…)
   calls `HTML#abort-the-ongoing-navigation`
   - under: While navigation's ongoing navigate event is not null:
   &gt; Abort the ongoing navigation given navigation.

4) [`HTML#abort-the-ongoing-navigation` step 7](…#ongoing-navigation-tracking:…)
   calls `HTML#abort-a-navigateevent`
   &gt; Abort event given error.

5) `HTML#abort-a-navigateevent` step 6 calls `HTML#event-navigateerror`
   &gt; Fire an event named navigateerror at navigation using ErrorEvent, with
     additional attributes initialized according to errorInfo.</code></pre></figure>

<p>I’ve wrapped those lines and shortened the URLs to fit; in the real output each hop is one long line and every link is a full deep link to that exact call site.</p>

<p>Every hop names the exact step number, quotes the step text, and tells you the condition it sits under. That last part matters more than it looks. Step 3.1 only runs while the ongoing navigate event is non-null, and knowing that is the difference between a path that exists on paper and a path your case actually took.</p>

<p>Eleven routes, though<sup id="fnref:1"><a href="#fn:1" class="footnote" rel="footnote" role="doc-noteref">1</a></sup>. Reading eleven of these back to back is not much better than the twenty tabs.</p>

<h2 id="three-zoom-levels">Three zoom levels</h2>

<p>This is where <code class="language-plaintext highlighter-rouge">webspec-index trace</code> gets genuinely nice, and it’s the part I want to draw attention to, because it’s easy to miss in the help text. The <code class="language-plaintext highlighter-rouge">--detail</code> flag changes how much of each route you get, and the three levels turn out to be three different ways of working rather than just three verbosity settings.</p>

<p>Ask the same question again with <code class="language-plaintext highlighter-rouge">--detail edges</code> and the prose falls away, leaving the skeleton:</p>

<figure class="highlight"><pre><code class="language-console" data-lang="console"><span class="gp">$</span><span class="w"> </span>webspec-index trace HTML#navigate HTML#event-navigateerror <span class="se">\</span>
<span class="go">    --detail edges --format markdown</span></code></pre></figure>

<figure class="highlight"><pre><code class="language-text" data-lang="text"># trace: `HTML#navigate` -&gt; `HTML#event-navigateerror`

Max depth 6, kind `step`. Found 11 trace(s).

## Trace 1 (5 hop(s))

1) `HTML#navigate` step 20 calls `HTML#set-the-ongoing-navigation`

2) `HTML#set-the-ongoing-navigation` step 2 calls `HTML#inform-the-navigation-api-about-aborting-navigation`

3) `HTML#inform-the-navigation-api-about-aborting-navigation` step 3.1 calls `HTML#abort-the-ongoing-navigation`

4) `HTML#abort-the-ongoing-navigation` step 7 calls `HTML#abort-a-navigateevent`

5) `HTML#abort-a-navigateevent` step 6 calls `HTML#event-navigateerror`

## Trace 2 (5 hop(s))

1) `HTML#navigate` step 22.4 calls `HTML#fire-a-push/replace/reload-navigate-event`

2) `HTML#fire-a-push/replace/reload-navigate-event` step 2 calls `HTML#inform-the-navigation-api-about-aborting-navigation`

...</code></pre></figure>

<p>Now you can read all eleven at once, and a shape appears that I could not see in the verbose output at all. There are five places inside <code class="language-plaintext highlighter-rouge">navigate</code> where a route starts:</p>

<table>
  <thead>
    <tr>
      <th style="text-align: left">step</th>
      <th style="text-align: left">calls</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style="text-align: left">15.1</td>
      <td style="text-align: left"><code class="language-plaintext highlighter-rouge">#navigate-fragid</code></td>
    </tr>
    <tr>
      <td style="text-align: left">20</td>
      <td style="text-align: left"><code class="language-plaintext highlighter-rouge">#set-the-ongoing-navigation</code></td>
    </tr>
    <tr>
      <td style="text-align: left">21.1</td>
      <td style="text-align: left"><code class="language-plaintext highlighter-rouge">#navigate-to-a-javascript:-url</code></td>
    </tr>
    <tr>
      <td style="text-align: left">22.4</td>
      <td style="text-align: left"><code class="language-plaintext highlighter-rouge">#fire-a-push/replace/reload-navigate-event</code></td>
    </tr>
    <tr>
      <td style="text-align: left">24.1</td>
      <td style="text-align: left"><code class="language-plaintext highlighter-rouge">#checking-if-unloading-is-canceled</code></td>
    </tr>
  </tbody>
</table>

<p>And all eleven finish on the same line:</p>

<figure class="highlight"><pre><code class="language-text" data-lang="text">`HTML#abort-a-navigateevent` step 6 calls `HTML#event-navigateerror`</code></pre></figure>

<p>There are exactly two ways into that step, from <code class="language-plaintext highlighter-rouge">HTML#abort-the-ongoing-navigation</code> step 7 and from <code class="language-plaintext highlighter-rouge">HTML#process-navigate-event-handler-failure</code> step 5. Eleven routes exist because three of the five entry points re-enter the same navigate event firing machinery from different directions, not because there are eleven genuinely different things going on.</p>

<p>That’s a useful thing to know before you start debugging. If a navigation is firing <code class="language-plaintext highlighter-rouge">navigateerror</code> and you want to find out why, you don’t instrument eleven places. You instrument the one step they all pass through and work backwards from there.</p>

<p>So the way I use it now is to start at <code class="language-plaintext highlighter-rouge">--detail edges</code> to find the shape, then drop back to the default once I know which route I care about and want to read the reasoning. The third level, <code class="language-plaintext highlighter-rouge">--detail compact</code>, drops the prose but keeps every anchor as a deep link to the exact call site, which is the form you want when you’re pasting a route into a bug report for someone else to follow.</p>

<h2 id="webspec-tracer">WebSpec Tracer</h2>

<p><code class="language-plaintext highlighter-rouge">webspec-index trace</code> answers a specific kind of question, and it’s worth being precise about which kind. You have to know both ends. That’s fine when you’re asking whether one thing can reach another, but a lot of the time I only know where I’m standing. I have a starting point, a bug in front of me, and no idea yet where the algorithm goes.</p>

<p>There’s also something <code class="language-plaintext highlighter-rouge">webspec-index trace</code> can’t do for you in principle. It finds routes through the spec text, statically. It doesn’t know which branch your case took, because that depends on what actually happened at runtime, and only you have that information.</p>

<p>So I wrote <a href="https://github.com/farre/webspec-tracer">WebSpec Tracer</a>, a Firefox extension that walks the specs with you rather than ahead of you. You give it a starting anchor and it shows you that algorithm with every linked term highlighted. Click one and it becomes the next hop in the trace, and the panel moves you into it. Click the wrong one and Back undoes it.</p>

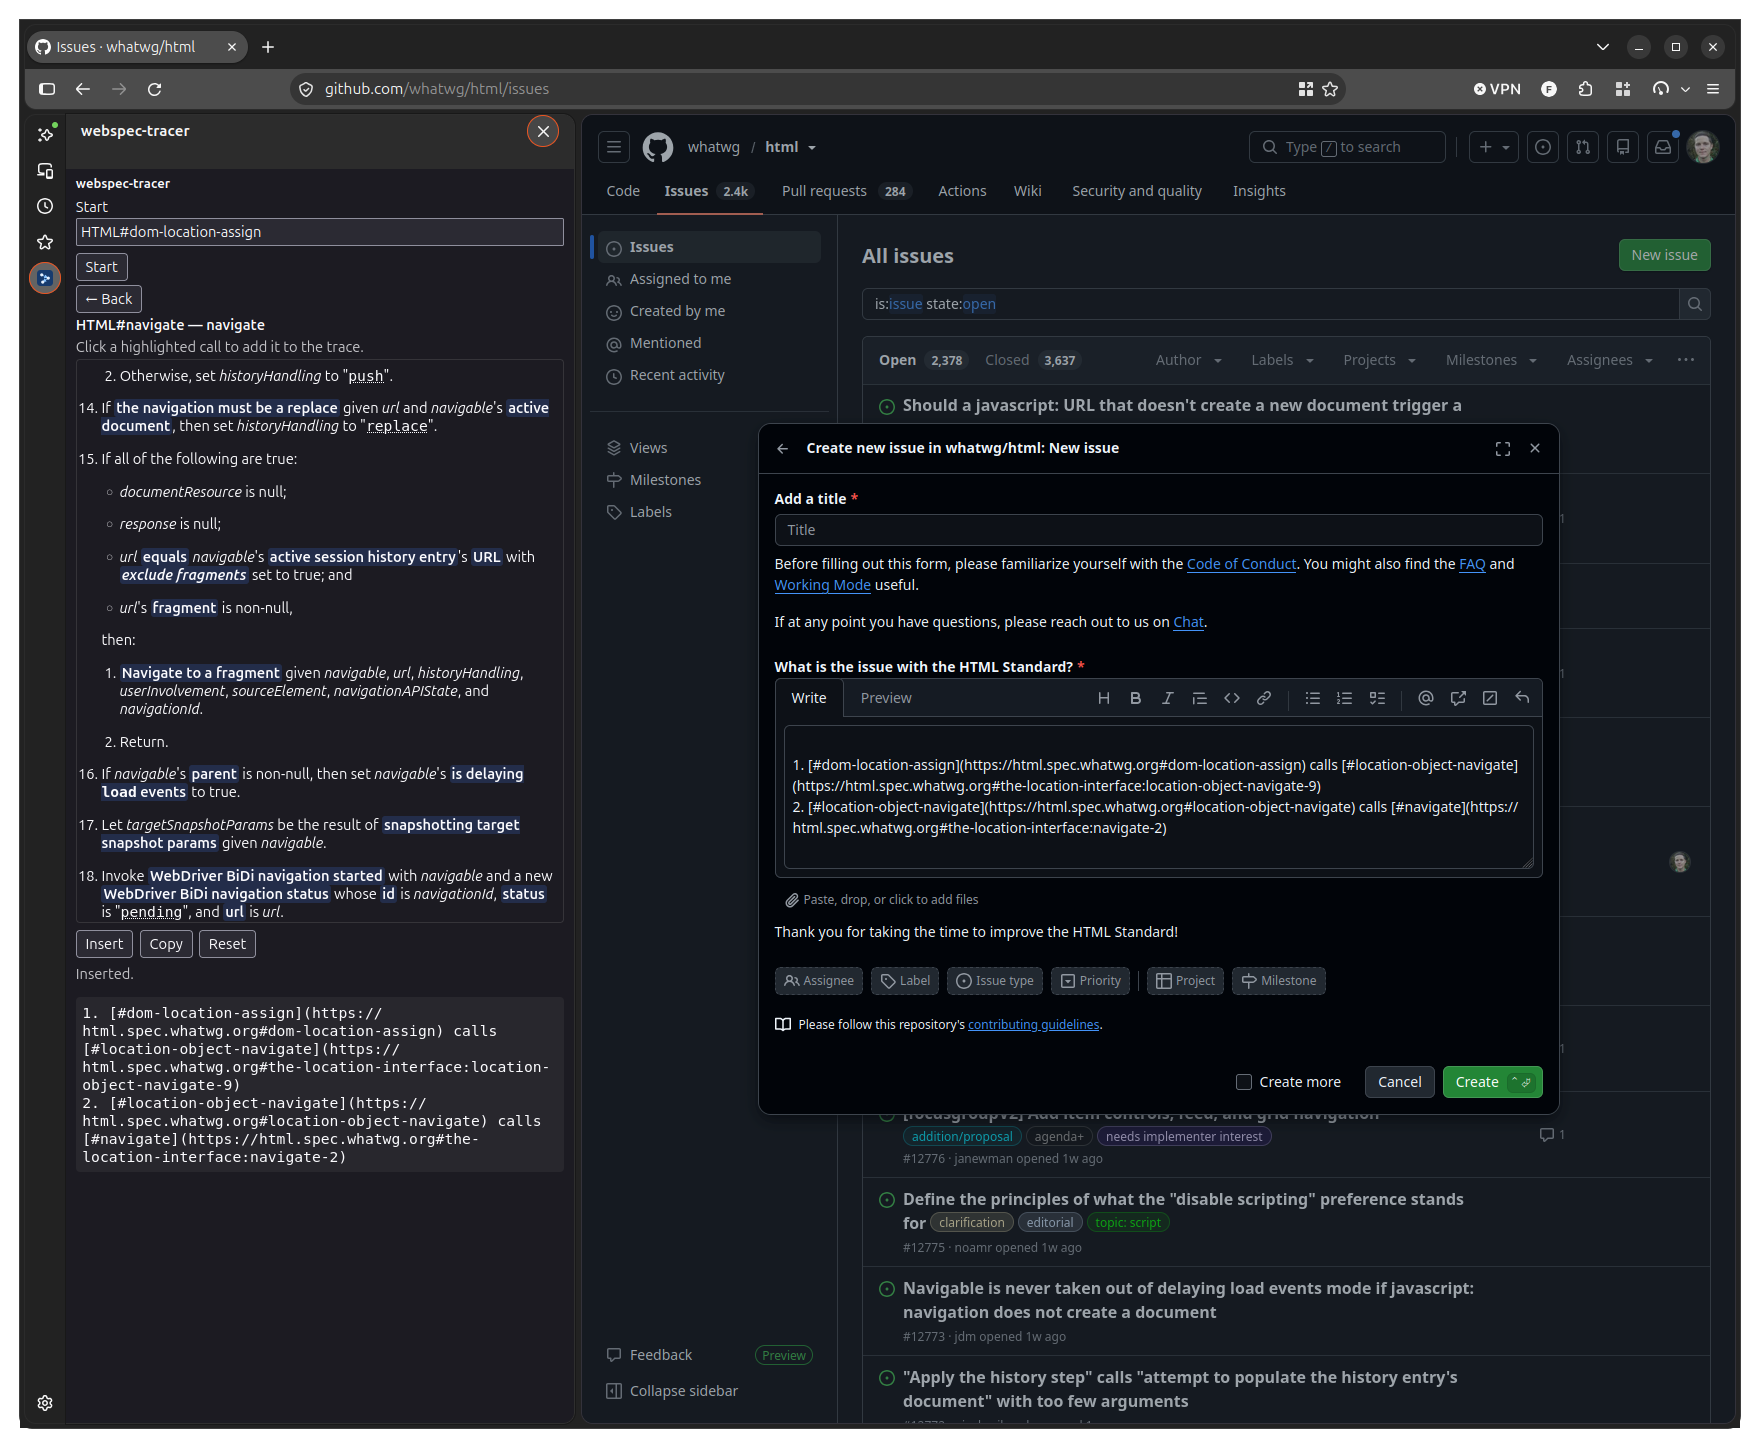
<p><img src="/assets/images/2026-08-17-tracing-web-specs/branch-point.png" alt="The WebSpec Tracer sidebar showing the navigate algorithm, with the linked terms in each step highlighted, next to a GitHub issue form containing the trace so far as markdown" /></p>

<p>The screenshot is a walk that started at <code class="language-plaintext highlighter-rouge">location.assign</code> and has arrived inside <code class="language-plaintext highlighter-rouge">navigate</code>. Step 15 is the interesting one. It runs only if four things are all true, that there’s no document resource, no response, the URL matches the current entry’s URL ignoring fragments, and the fragment is non-null. If all four hold, it navigates to a fragment and returns. Otherwise the algorithm keeps going into the full navigation path below.</p>

<p>No tool can decide that for me. Whether my bug went left or right at step 15 depends on the page and on what the user did. But the extension puts the decision in front of me with the alternatives visible, which is precisely what I was failing to do for myself with twenty tabs open.</p>

<p>The trace builds up in the panel underneath as markdown, with every anchor pointing at the exact call site. That box is a display rather than a text field, so there are buttons for getting the trace out of it. Copy does what you’d expect. Insert is the one I actually use, and it’s the reason the extension lives in the sidebar: it writes the markdown straight into whichever field you have focused on the page, so you can have a spec issue open next to the panel and drop the trace into it without going near the clipboard. Reset clears everything and starts over.</p>

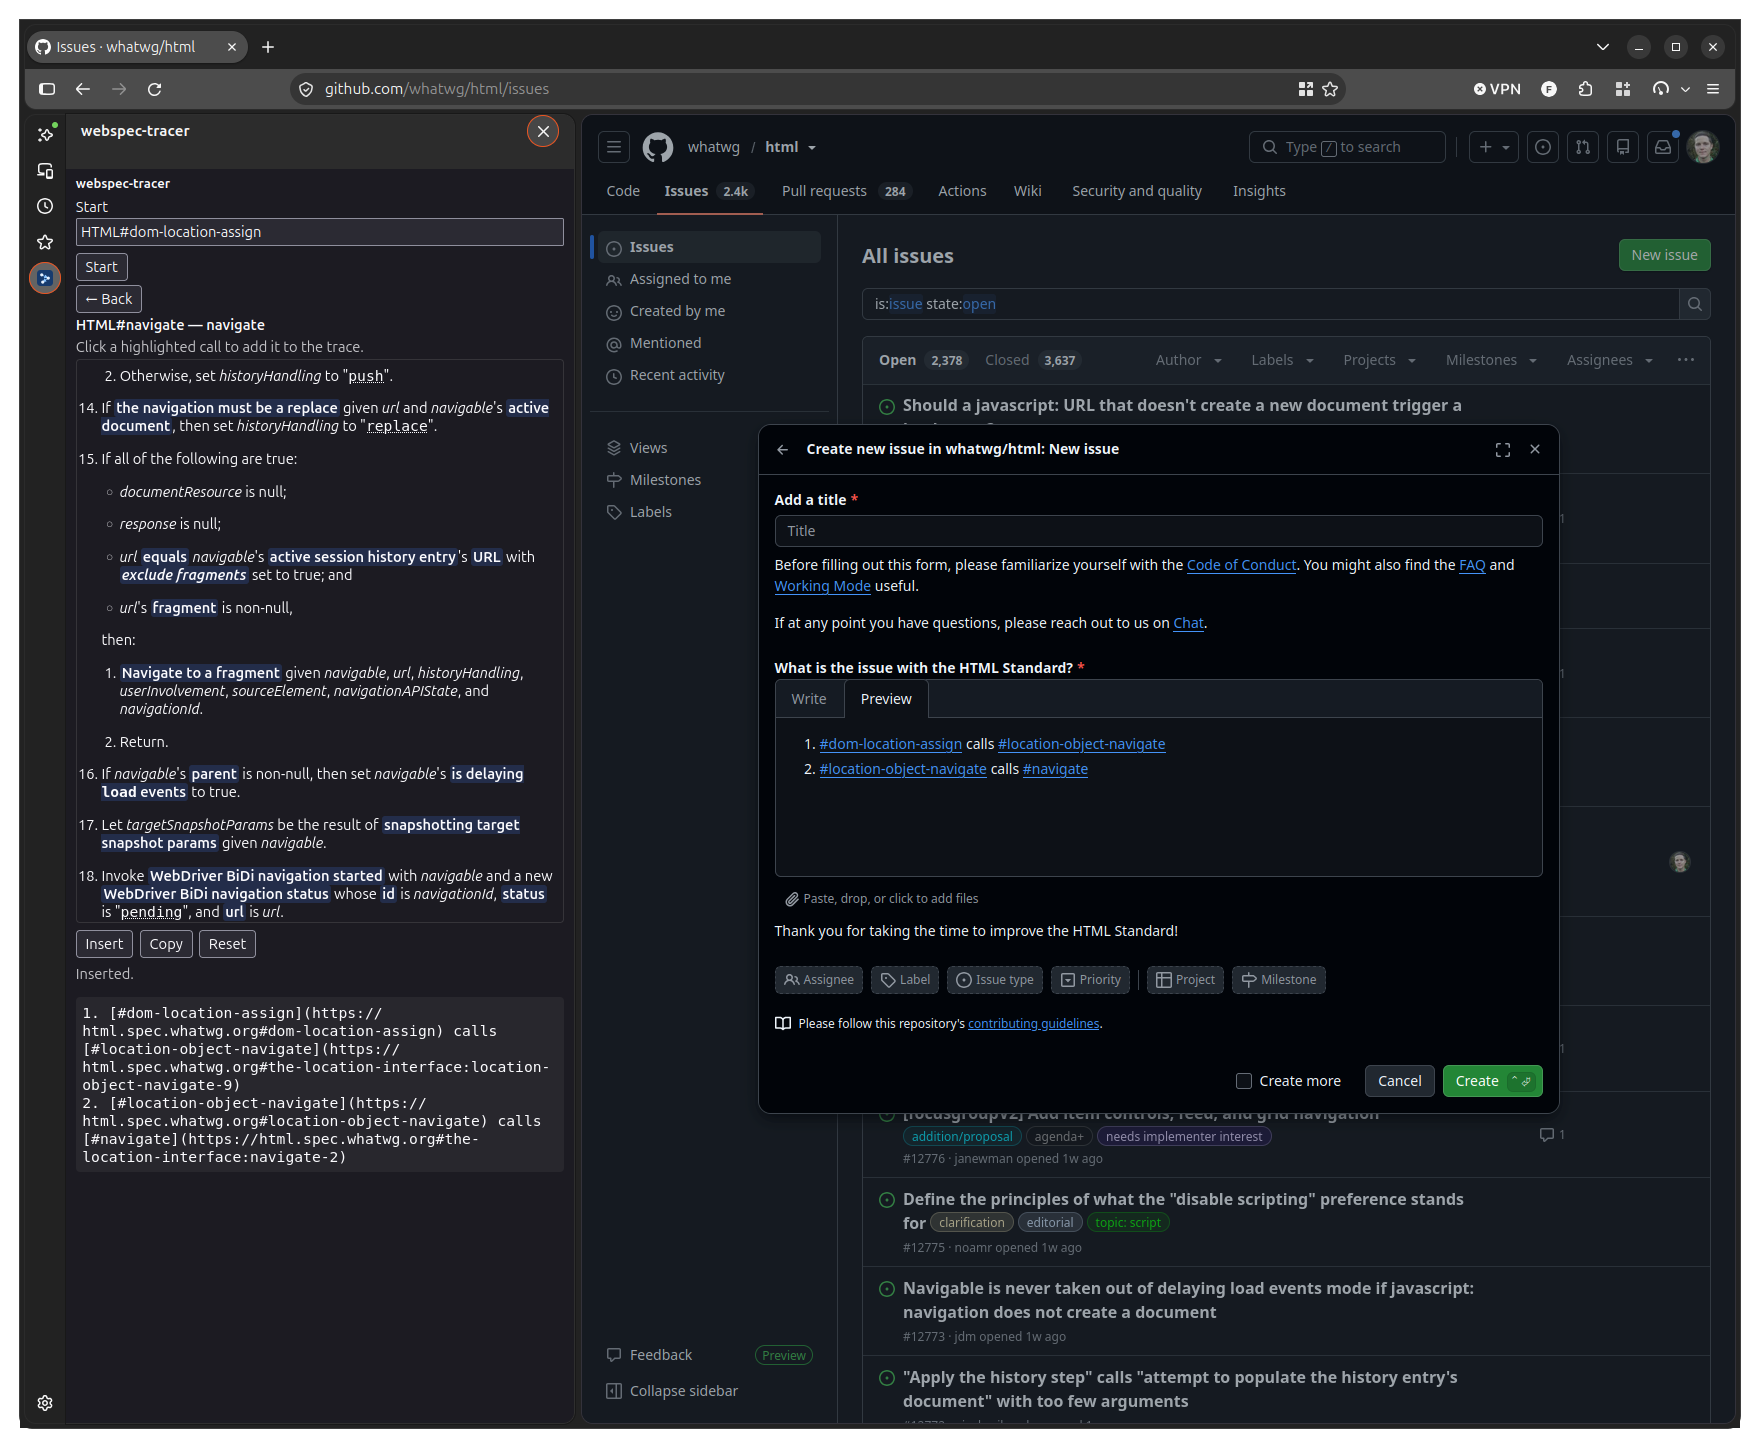
<p><img src="/assets/images/2026-08-17-tracing-web-specs/branch-preview.png" alt="The same panel, with the GitHub issue switched to the Preview tab, showing the two hops rendered as linked spec anchors" /></p>

<p>Switch the issue over to Preview and there are the same two hops, rendered, each one a link into the spec. That’s most of the reason I built the thing. Explaining a route through an algorithm in prose is miserable, and the version you retype by hand is always slightly wrong. This way what I hand over is exactly what I walked.</p>

<p>One more thing worth knowing, about the anchors themselves. The starting one has to say which spec it’s in, so <code class="language-plaintext highlighter-rouge">HTML#dom-location-assign</code> rather than just <code class="language-plaintext highlighter-rouge">dom-location-assign</code>, but after that the extension works it out as it goes. Anything that turns up in the trace without a prefix is in the spec you started from, and a prefix appears when the trace crosses a boundary:</p>

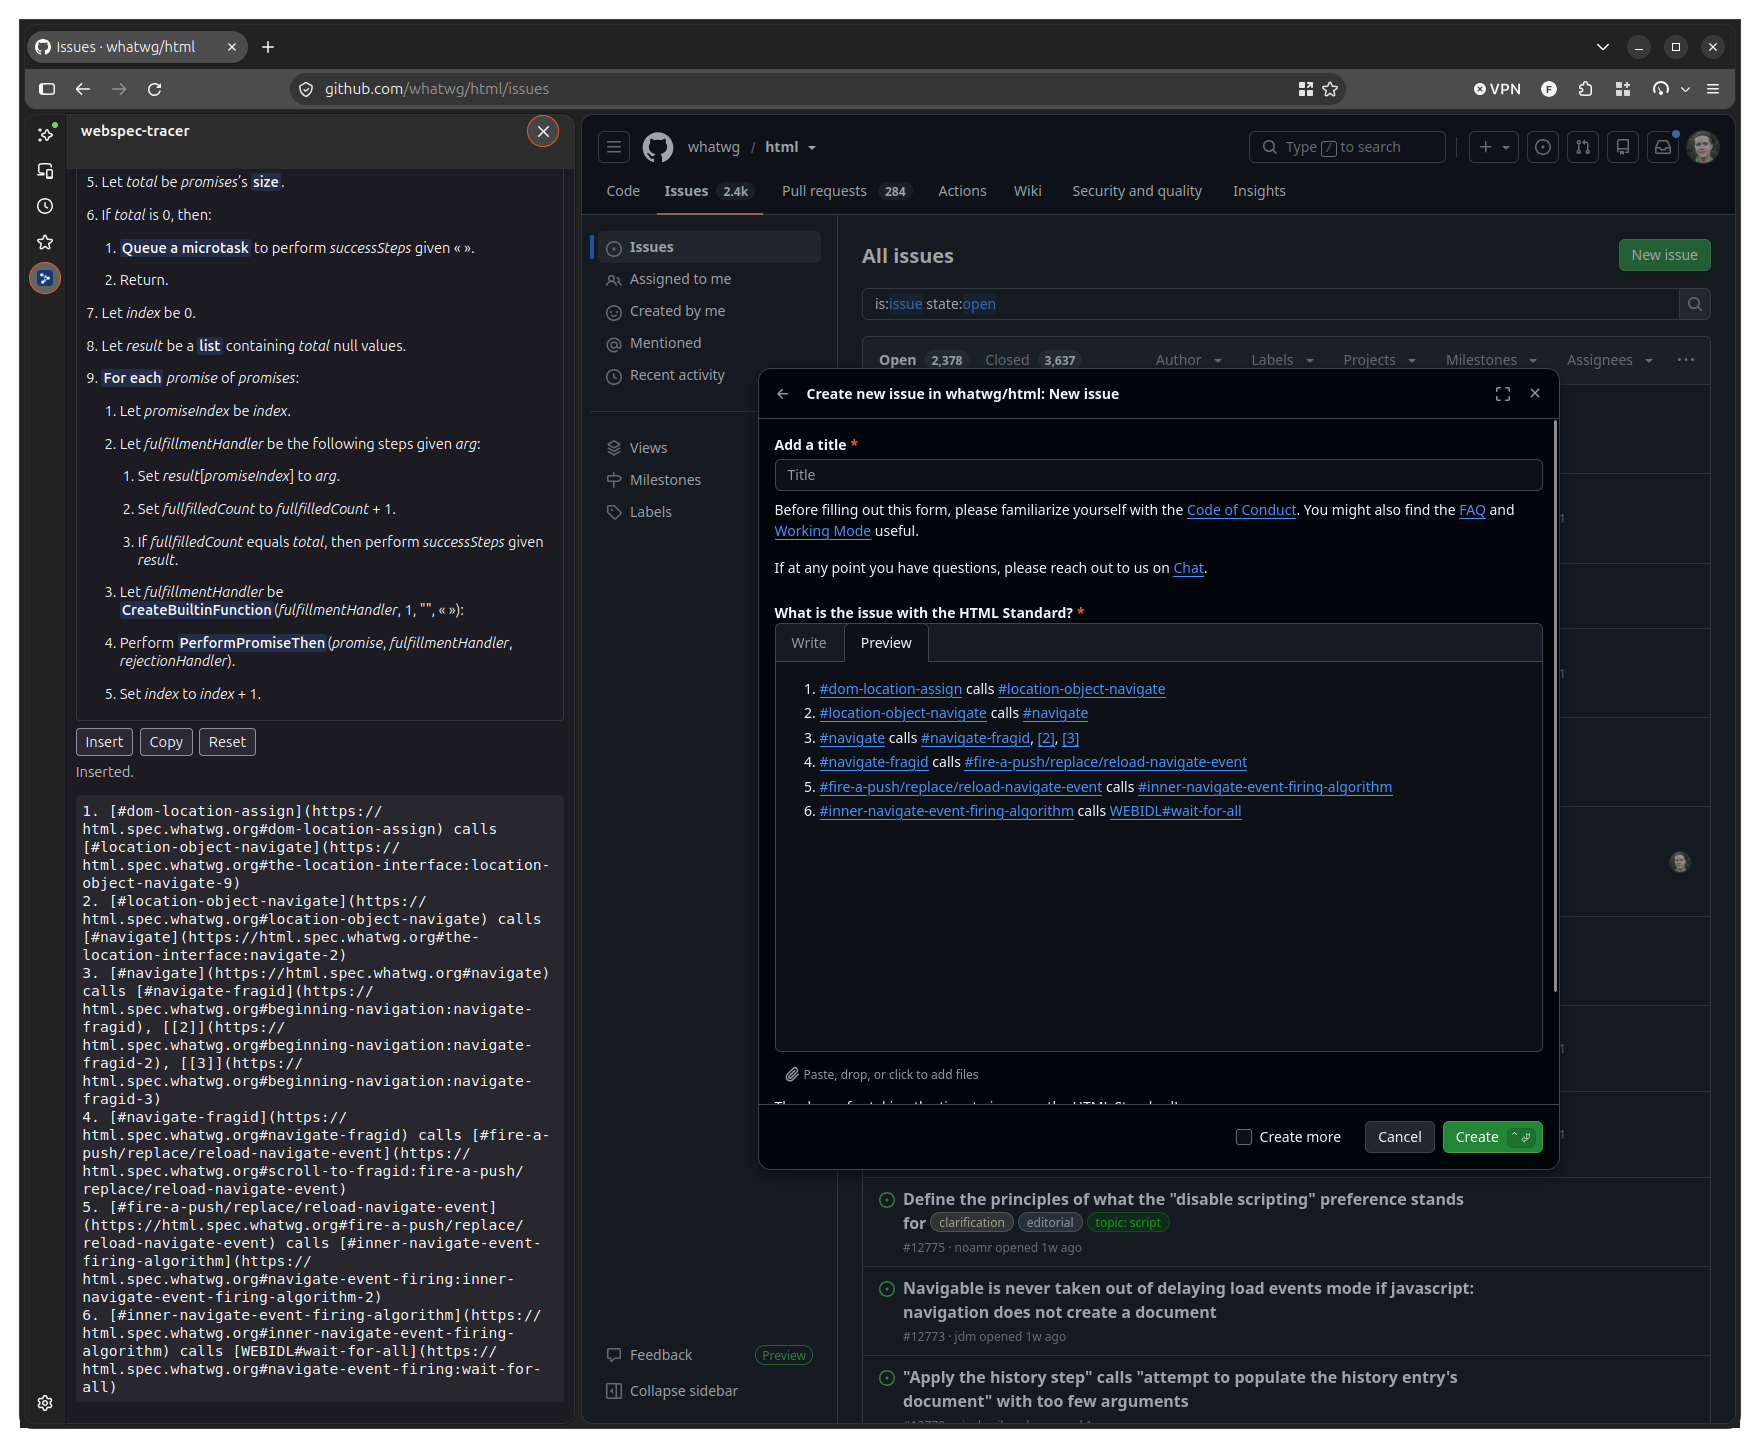
<p><img src="/assets/images/2026-08-17-tracing-web-specs/cross-spec.png" alt="The panel showing WebIDL's wait for all algorithm, with a six hop trace whose last line ends in WEBIDL#wait-for-all" /></p>

<p>That’s the same walk carried a few hops further. Hop 3 is that step 15 decision, taken, and the last line is <code class="language-plaintext highlighter-rouge">WEBIDL#wait-for-all</code>. Somewhere in the navigate event firing the trace left HTML entirely, and the prefix is the only thing that tells me so. The panel on the left has stopped showing me HTML too, and is now sitting in WebIDL. That’s easy to lose track of when you’re clicking through by hand, and it’s usually the moment a question stops being about HTML and starts being about something else.</p>

<h2 id="when-one-call-happens-twelve-times">When one call happens twelve times</h2>

<p>Sometimes an algorithm invokes another one from many different places, and a trace has to say something sensible about that. This was in the design from the start, and the answer it arrived at is to do what the spec already does. Start at <code class="language-plaintext highlighter-rouge">HTML#update-the-image-data</code> and follow it to <code class="language-plaintext highlighter-rouge">HTML#abort-the-image-request</code>:</p>

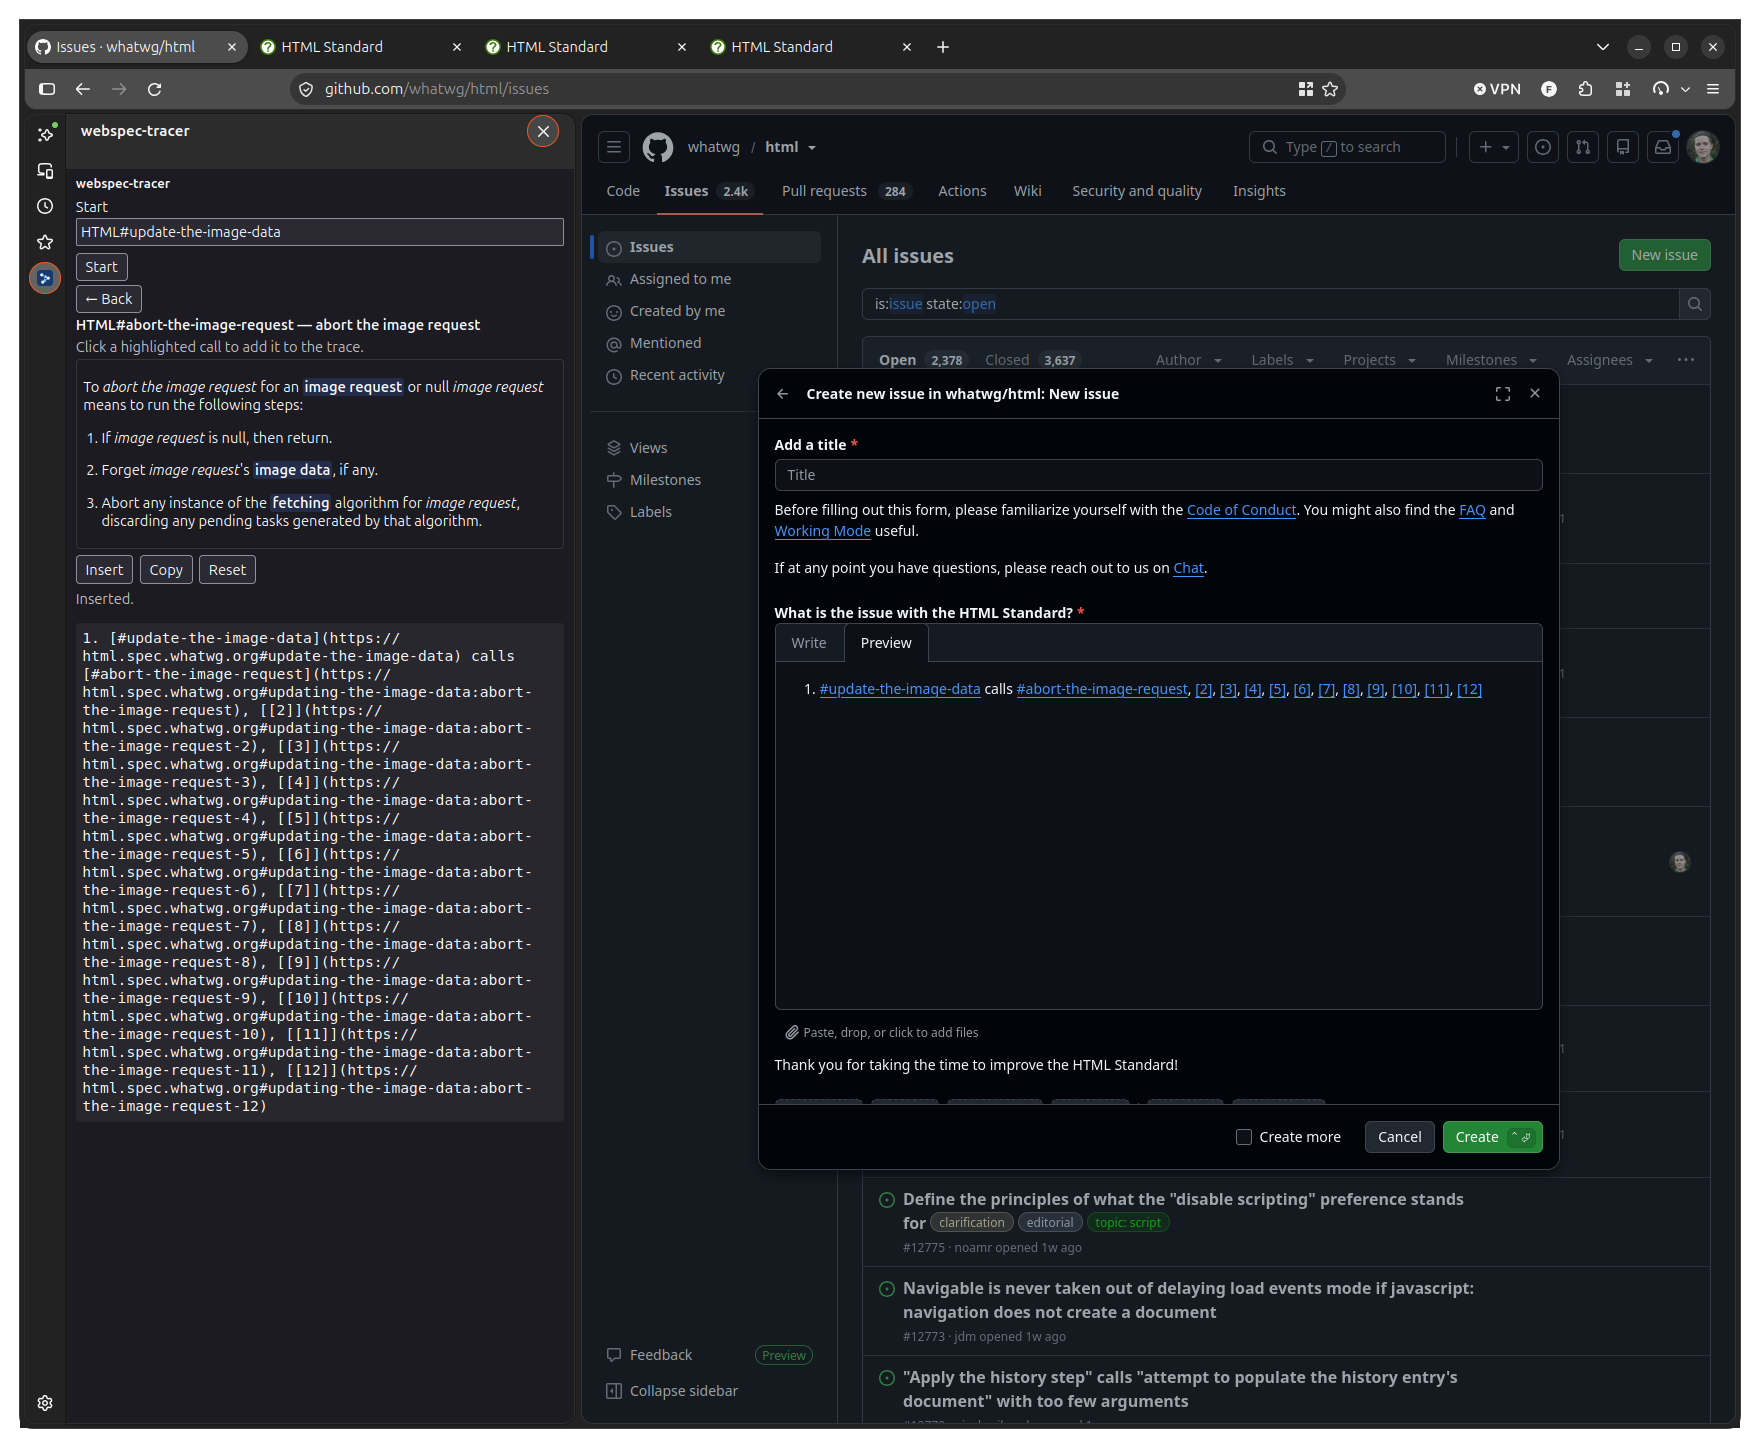
<p><img src="/assets/images/2026-08-17-tracing-web-specs/multi-branch.png" alt="The panel showing the abort the image request algorithm, with a single trace line listing twelve numbered call sites" /></p>

<p><code class="language-plaintext highlighter-rouge">HTML#abort-the-image-request</code> is invoked from twelve separate places inside <code class="language-plaintext highlighter-rouge">HTML#update-the-image-data</code>. The extension doesn’t make me choose one, and it doesn’t flatten them into a single link either. It records the hop once and hangs all twelve call sites off it as numbered links, so the line reads <code class="language-plaintext highlighter-rouge">#update-the-image-data calls #abort-the-image-request, [2], [3]</code> and onwards to <code class="language-plaintext highlighter-rouge">[12]</code>, each number pointing at its own anchor.</p>

<p>The numbering isn’t invented. It’s the spec’s own scheme for repeated references: the anchors run <code class="language-plaintext highlighter-rouge">#abort-the-image-request</code>, then <code class="language-plaintext highlighter-rouge">-2</code>, <code class="language-plaintext highlighter-rouge">-3</code>, and so on up to <code class="language-plaintext highlighter-rouge">-12</code>. All the trace does is carry that through, so a hop in the output identifies call sites the same way the spec identifies them, and the numbers mean the same thing in both places.</p>

<p>That also keeps the trace honest. The hop happened, and that’s true whichever of the twelve fired, but the fact that there are twelve is worth knowing on its own, and anyone reading can go and check any one of them. Writing this out by hand you would link the first and lose the other eleven without ever noticing. The same thing is visible in the previous screenshot, where hop 3 reads <code class="language-plaintext highlighter-rouge">#navigate calls #navigate-fragid, [2], [3]</code>.</p>

<p><code class="language-plaintext highlighter-rouge">webspec-index trace</code> deals with the same situation the other way round. Ask it the same question and you get twelve separate one hop traces, each naming its own step number, step 2, then 7.4.2, then 11.1, and so on down the algorithm. Neither is wrong. The command line is telling you which steps, and the extension is keeping your trace to one line while preserving every place it could have come from.</p>

<h2 id="which-one-when">Which one, when</h2>

<p>They divide up cleanly enough that I don’t think about it much any more. If I know both ends and want to know what’s between them, or how many different routes there are, that’s <code class="language-plaintext highlighter-rouge">webspec-index trace</code>. If I know where I’m starting and want to find out where it goes, that’s the extension.</p>

<p>The one I underused at first was <code class="language-plaintext highlighter-rouge">--detail edges</code>. Asking a broad question and then zooming out far enough to see the answer’s shape is a different move from following a single path carefully, and it’s the one that has surprised me most often, usually by showing me that several things I thought were separate all funnel through the same step.</p>

<h2 id="getting-them">Getting them</h2>

<p>webspec-index is on crates.io:</p>

<figure class="highlight"><pre><code class="language-bash" data-lang="bash">cargo binstall webspec-index</code></pre></figure>

<p>It builds its index as it goes, so the first trace into a corner you haven’t visited before pauses briefly to fetch and index the specs the route touches. After that it’s fast.</p>

<p>WebSpec Tracer is on <a href="https://addons.mozilla.org/en-US/firefox/addon/webspec-tracer/">addons.mozilla.org</a>, and the source is on <a href="https://github.com/farre/webspec-tracer">GitHub</a>. It lives in the sidebar, toggled with <code class="language-plaintext highlighter-rouge">Ctrl+Shift+U</code>, so you can keep it open next to whatever you’re reading.</p>

<p>Both are worth a try if you spend any time at all reading specs, whether you’re implementing them, arguing with them, or just trying to find out whether the browser is wrong or you are.</p>

<h4 id="notes">Notes</h4>

<div class="footnotes" role="doc-endnotes">
  <ol>
    <li id="fn:1">
      <p>Eleven is what you get at the default maximum depth of six hops. Raise it and there are more. <a href="#fnref:1" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
  </ol>
</div>

<script src="https://utteranc.es/client.js" repo="farre/blog" issue-term="og:title" label="comments" theme="github-light" crossorigin="anonymous" async="">
</script>]]></content><author><name>Andreas Farre</name></author><category term="mozilla" /><category term="web specs" /><category term="tooling" /><summary type="html"><![CDATA[A bug comes in, or someone shows me a page doing something surprising, and the question is always the same one. Is that what the spec says? Not what we all assume it says, and not what Gecko happens to do, but what the algorithm actually does when you follow it step by step. So I open html.spec.whatwg.org, find the entry point, and start reading. Twenty tabs later I have usually lost the thread.]]></summary></entry><entry><title type="html">Session History Diagrams in Firefox DevTools</title><link href="https://blog.farre.se/posts/2026/06/01/session-history-diagrams/" rel="alternate" type="text/html" title="Session History Diagrams in Firefox DevTools" /><published>2026-06-01T00:00:00+00:00</published><updated>2026-06-01T00:00:00+00:00</updated><id>https://blog.farre.se/posts/2026/06/01/session-history-diagrams</id><content type="html" xml:base="https://blog.farre.se/posts/2026/06/01/session-history-diagrams/"><![CDATA[<p>I’ve spent a lot of time at Mozilla working on session history, the machinery that keeps track of where you’ve been so the back and forward buttons do something sensible. It’s one of those parts of the browser that sounds simple from the outside and turns out to be anything but. Once you add iframes, nested iframes, and the subtle rules about when a navigation creates a new entry versus replacing the current one, the state you’re reasoning about gets large and hard to hold in your head.</p>

<!-- more -->

<p>For years my main tool for understanding that state was reading code and printing things to a log. That works, but it’s slow, and it never quite shows you the shape of the thing. So I built a way to <em>see</em> it: a new DevTools panel in Firefox Nightly called Session History Diagrams.</p>

<h2 id="enabling-it">Enabling it</h2>

<p>The panel is available in Firefox today, behind a pref. It’s been there in some form since Firefox 150, growing more stable with each release. To turn it on, set <code class="language-plaintext highlighter-rouge">devtools.application.sessionHistory.enabled</code> to true in <code class="language-plaintext highlighter-rouge">about:config</code>, then reload DevTools. The new panel lives under the Application tab, next to Service Workers and Manifest, and it draws the browser’s session history as a diagram that updates as you navigate.</p>

<p>Since Firefox 153 it also works over remote debugging. Connect to a device from <code class="language-plaintext highlighter-rouge">about:debugging</code> and you can watch the session history of a page running on Android, the same as you would on the desktop.</p>

<h2 id="jake-diagrams">Jake diagrams</h2>

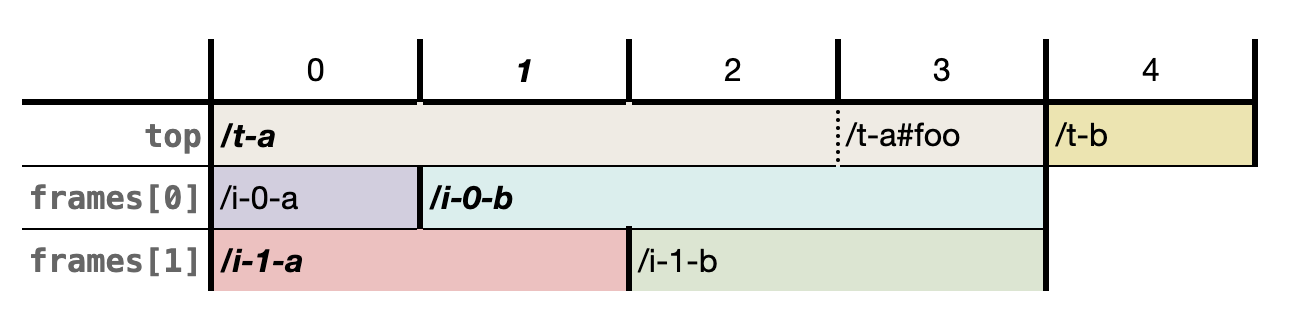
<p>I didn’t invent the idea of drawing this. The HTML spec already has a notation for it, called a <a href="https://html.spec.whatwg.org/#jake-diagrams">Jake diagram</a> after <a href="https://jakearchibald.com/">Jake Archibald</a>, and that’s where I started. It’s a tabular notation where columns represent steps in session history, and rows represent navigables (the top-level browsing context plus any iframes). Background colors identify documents, a fresh color marking a new document loaded in that navigable, and the current step is shown in bold. It’s a genuinely useful way to capture multi-navigable interactions that are otherwise hard to describe in prose.</p>

<p><img src="/assets/images/2026-06-01-session-history-diagrams/jake-diagram.png" alt="A Jake diagram showing a top-level navigable and two iframes across five history steps" /></p>

<p>These diagrams don’t have to be drawn by hand. <a href="https://github.com/domenic">Domenic Denicola</a>, one of the HTML spec editors, built a <a href="https://github.com/domenic/jake-diagram-generator">Jake diagram generator</a> that turns a description of a navigation sequence into a rendered diagram. That’s where I first started playing with a more dynamic approach to the visualization. The thing I missed the most was being able to build a history up step by step rather than describe a finished sequence all at once. So I wrote <a href="https://github.com/farre/web-tools/tree/master/rejake">rejake</a>, a small tool that draws diagrams in the same style<sup id="fnref:1"><a href="#fn:1" class="footnote" rel="footnote" role="doc-noteref">1</a></sup>, but lets you construct the history one step at a time.</p>

<p>But rejake, like the spec’s diagrams and Domenic’s generator before it, was stuck with a limitation the spec itself admits to, that they only work with a single level of nesting. That was exactly my problem. Real pages nest iframes inside iframes, and the bugs I was chasing usually lived down in that deeper nesting, precisely where the diagram stops being able to help. And however I drew them, I was still typing the history out by hand. It’s a short step from there to wanting the diagram to draw itself from the browser’s actual session history instead<sup id="fnref:2"><a href="#fn:2" class="footnote" rel="footnote" role="doc-noteref">2</a></sup>.</p>

<h2 id="firefox-session-history-diagrams">Firefox Session History Diagrams</h2>

<p>So the panel extends Jake diagrams to handle arbitrary nesting. Every column is a step in the session history. Every row is a frame, listed in pre-order from the frame tree: top-level document first, then its first iframe, then that iframe’s children, and so on. The current entry is highlighted in blue, and the diagram updates live as you navigate.</p>

<div style="overflow:hidden; display:inline-block; max-width:100%"><video src="/assets/videos/2026-06-01-session-history-diagrams/demo.mp4" style="display:block; max-width:100%" muted="" autoplay="" loop="" playsinline=""></video></div>

<p>The recording above is an ordinary bit of browsing, a handful of pages visited one after another. The top row tracks the page you’re actually looking at, and the current position is the one in blue. The interesting part is everything underneath that top row.</p>

<p>Some of those pages didn’t just load a single document. They pulled in nested frames of their own, and the diagram stacks those below the page that owns them. None of that is visible in the address bar or anywhere in the page chrome, and the frames come and go as you move through the history. Normally you’d have no way of knowing they were ever there. Here you can read straight off the diagram which frames a given step carried, when each one entered, and when it dropped away again.</p>

<h2 id="who-else-might-want-this">Who else might want this</h2>

<p>I built this for myself, working on Gecko’s session history internals, where being able to watch the diagram change while reproducing a bug turns opaque state into something I can point at. But it turns out I’m not the only one who hits this wall. Plenty of people working elsewhere in Gecko, anywhere near navigation, end up reasoning about the same state, and now we all share one picture of it.</p>

<p>If you build single-page applications, or work with the <a href="https://developer.mozilla.org/en-US/docs/Web/API/History_API">History API</a> or <a href="https://developer.mozilla.org/en-US/docs/Web/API/Navigation_API">Navigation API</a>, you’ve probably run into the same kind of confusion from the other side. A push where you expected a replace, a missing history entry, an iframe that accumulated entries unexpectedly. These are hard to reason about without seeing the state directly, and that’s exactly what the diagram gives you.</p>

<p>Session history isn’t a Firefox-specific problem either. Every engine implements the same part of the HTML spec, and Jake diagrams come from that shared spec. The panel only ever shows Firefox’s state, but the rules are the same everywhere, so if you work on another engine it can still be a useful reference for how one implementation behaves. It’s often the only practical way to surface an interoperability difference, which might be a bug in any of the engines, but stays hidden until you can actually see it.</p>

<h2 id="thanks">Thanks</h2>

<p>A big thanks to <a href="https://github.com/nchevobbe">Nicolas Chevobbe</a>, whose assistance was invaluable in getting the DevTools integration right. The work, including what’s still to come, is tracked in <a href="https://bugzilla.mozilla.org/show_bug.cgi?id=2015726">Bug 2015726</a>. There’s a fair bit still on that list, like marking whether a step was a push or a replace, surfacing back/forward cache state, tying the diagram into the Network and Inspector panels, and more, all heading toward fuller DevTools support for Navigation and Session History.</p>

<h4 id="notes">Notes</h4>

<div class="footnotes" role="doc-endnotes">
  <ol>
    <li id="fn:1">
      <p>Which, naturally, meant re-implementing the whole of Session History along the way. <a href="#fnref:1" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:2">
      <p>Getting nerd-sniped by <a href="https://github.com/jnjaeschke/">Jan Jaeschke</a> definitely contributed as well. <a href="#fnref:2" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
  </ol>
</div>

<script src="https://utteranc.es/client.js" repo="farre/blog" issue-term="og:title" label="comments" theme="github-light" crossorigin="anonymous" async="">
</script>]]></content><author><name>Andreas Farre</name></author><category term="mozilla" /><category term="session history" /><category term="navigation" /><category term="jake diagram" /><summary type="html"><![CDATA[I’ve spent a lot of time at Mozilla working on session history, the machinery that keeps track of where you’ve been so the back and forward buttons do something sensible. It’s one of those parts of the browser that sounds simple from the outside and turns out to be anything but. Once you add iframes, nested iframes, and the subtle rules about when a navigation creates a new entry versus replacing the current one, the state you’re reasoning about gets large and hard to hold in your head.]]></summary></entry><entry><title type="html">How to make Firefox builds1 17% faster2</title><link href="https://blog.farre.se/posts/2026/04/10/caching-webidl-codegen/" rel="alternate" type="text/html" title="How to make Firefox builds1 17% faster2" /><published>2026-04-10T00:00:00+00:00</published><updated>2026-04-10T00:00:00+00:00</updated><id>https://blog.farre.se/posts/2026/04/10/caching-webidl-codegen</id><content type="html" xml:base="https://blog.farre.se/posts/2026/04/10/caching-webidl-codegen/"><![CDATA[<p>In the <a href="/posts/2026/04/09/buildcache-with-mach/">previous post</a>, I mentioned that buildcache has some unique properties compared to ccache and sccache. One of them is its <a href="https://gitlab.com/bits-n-bites/buildcache/-/blob/master/doc/lua.md">Lua plugin system</a>, which lets you write custom wrappers for programs that aren’t compilers in the traditional sense. With <a href="https://bugzilla.mozilla.org/show_bug.cgi?id=2027655">Bug 2027655</a> now merged, we can use this to cache Firefox’s WebIDL binding code generation.</p>

<!-- more -->

<h2 id="whats-the-webidl-step">What’s the WebIDL step?</h2>

<p>When you build Firefox, one of the earlier steps runs <code class="language-plaintext highlighter-rouge">python3 -m mozbuild.action.webidl</code> to generate C++ binding code from hundreds of <code class="language-plaintext highlighter-rouge">.webidl</code> files. It produces thousands of output files: headers, cpp files, forward declarations, event implementations, and so on. The step isn’t terribly slow on its own, but it runs on every clobber build, and the output is entirely deterministic given the same inputs. That makes it a perfect candidate for caching.</p>

<p>The problem was that the compiler cache was never passed to this step. Buildcache was only wrapping actual compiler invocations, not the Python codegen.</p>

<h2 id="the-change">The change</h2>

<p>The fix in <a href="https://bugzilla.mozilla.org/show_bug.cgi?id=2027655">Bug 2027655</a> is small. In <code class="language-plaintext highlighter-rouge">dom/bindings/Makefile.in</code>, we now conditionally pass <code class="language-plaintext highlighter-rouge">$(CCACHE)</code> as a command wrapper to the <code class="language-plaintext highlighter-rouge">py_action</code> call:</p>

<figure class="highlight"><pre><code class="language-make" data-lang="make"><span class="nv">WEBIDL_CCACHE</span><span class="o">=</span>
<span class="k">ifdef</span> <span class="nv">MOZ_USING_BUILDCACHE</span>
<span class="nv">WEBIDL_CCACHE</span><span class="o">=</span><span class="p">$(</span>CCACHE<span class="p">)</span>
<span class="k">endif</span>

<span class="nl">webidl.stub</span><span class="o">:</span> <span class="nf">$(codegen_dependencies)</span>
	<span class="p">$(</span>call py_action,webidl <span class="p">$(</span>relativesrcdir<span class="p">)</span>,<span class="p">$(</span>srcdir<span class="p">)</span>,,<span class="p">$(</span>WEBIDL_CCACHE<span class="p">))</span>
	<span class="p">@$(</span>TOUCH<span class="p">)</span> <span class="nv">$@</span></code></pre></figure>

<p>The <code class="language-plaintext highlighter-rouge">py_action</code> macro in <code class="language-plaintext highlighter-rouge">config/makefiles/functions.mk</code> is what runs Python build actions. The ability to pass a command wrapper as a fourth argument was also introduced in this bug. When buildcache is configured as the compiler cache, this means the webidl action is invoked as <code class="language-plaintext highlighter-rouge">buildcache python3 -m mozbuild.action.webidl ...</code> instead of just <code class="language-plaintext highlighter-rouge">python3 -m mozbuild.action.webidl ...</code>. That’s all buildcache needs to intercept it.</p>

<p>Note the <code class="language-plaintext highlighter-rouge">ifdef MOZ_USING_BUILDCACHE</code> guard. This is specific to buildcache because ccache and sccache don’t have a mechanism for caching arbitrary commands. Buildcache does, through its Lua wrappers.</p>

<h2 id="the-lua-wrapper">The Lua wrapper</h2>

<p>Buildcache’s Lua plugin system lets you write a script that tells it how to handle a program it doesn’t natively understand. The wrapper for WebIDL codegen, <a href="https://github.com/farre/buildcache-wrappers/blob/main/mozilla/webidl.lua">webidl.lua</a>, needs to answer a few questions for buildcache:</p>

<ul>
  <li><strong>Can I handle this command?</strong> Match on <code class="language-plaintext highlighter-rouge">mozbuild.action.webidl</code> in the argument list.</li>
  <li><strong>What are the inputs?</strong> All the <code class="language-plaintext highlighter-rouge">.webidl</code> source files, plus the Python codegen scripts. These come from <code class="language-plaintext highlighter-rouge">file-lists.json</code> (which <code class="language-plaintext highlighter-rouge">mach</code> generates) and <code class="language-plaintext highlighter-rouge">codegen.json</code> (which tracks the Python dependencies from the previous run).</li>
  <li><strong>What are the outputs?</strong> All the generated binding headers, cpp files, event files, and the codegen state files. Again derived from <code class="language-plaintext highlighter-rouge">file-lists.json</code>.</li>
</ul>

<p>With that information, buildcache can hash the inputs, check the cache, and either replay the cached outputs or run the real command and store the results.</p>

<p>The wrapper uses buildcache’s <code class="language-plaintext highlighter-rouge">direct_mode</code> capability, meaning it hashes input files directly rather than relying on preprocessed output. This is the right approach here since we’re not dealing with a C preprocessor but with a Python script that reads <code class="language-plaintext highlighter-rouge">.webidl</code> files.</p>

<h2 id="numbers">Numbers</h2>

<p>Here are build times for <code class="language-plaintext highlighter-rouge">./mach build</code> on Linux, comparing compiler cachers. Each row shows a clobber build with an empty cache (cold), followed by a clobber build with a filled cache (warm):</p>

<table>
  <thead>
    <tr>
      <th style="text-align: left">tool</th>
      <th style="text-align: left">cold</th>
      <th style="text-align: left">warm</th>
      <th style="text-align: left">with plugin</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style="text-align: left">none</td>
      <td style="text-align: left">5m35s</td>
      <td style="text-align: left">n/a</td>
      <td style="text-align: left">n/a</td>
    </tr>
    <tr>
      <td style="text-align: left">ccache</td>
      <td style="text-align: left">5m42s</td>
      <td style="text-align: left">3m21s</td>
      <td style="text-align: left">n/a</td>
    </tr>
    <tr>
      <td style="text-align: left">sccache</td>
      <td style="text-align: left">9m38s</td>
      <td style="text-align: left">2m49s</td>
      <td style="text-align: left">n/a</td>
    </tr>
    <tr>
      <td style="text-align: left">buildcache</td>
      <td style="text-align: left">5m43s</td>
      <td style="text-align: left">1m27s</td>
      <td style="text-align: left">1m12s</td>
    </tr>
  </tbody>
</table>

<p>The “with plugin” column is buildcache with the <code class="language-plaintext highlighter-rouge">webidl.lua</code> wrapper active. It shaves another 15 seconds<sup id="fnref:1"><a href="#fn:1" class="footnote" rel="footnote" role="doc-noteref">1</a></sup>, bringing the total down to 1m12s<sup id="fnref:2"><a href="#fn:2" class="footnote" rel="footnote" role="doc-noteref">2</a></sup>. Not a revolutionary improvement on its own, but it demonstrates the mechanism. The WebIDL step is just the first Python action to get this treatment; there are other codegen steps in the build that could benefit from the same approach.</p>

<p>More broadly, these numbers show buildcache pulling well ahead on warm builds. Going from a 5m35s clean build to a 1m12s cached rebuild is a nice improvement to the edit-compile-test cycle.</p>

<p>These are single runs on one machine, not rigorous benchmarks, but the direction is clear enough.</p>

<h2 id="setting-it-up">Setting it up</h2>

<p>If you’re already using buildcache with <code class="language-plaintext highlighter-rouge">mach</code>, the Makefile change is available when updating to today’s central. To enable the Lua wrapper, clone the <a href="https://github.com/farre/buildcache-wrappers">buildcache-wrappers</a> repo and point buildcache at it via <code class="language-plaintext highlighter-rouge">lua_paths</code> in <code class="language-plaintext highlighter-rouge">~/.buildcache/config.json</code>:</p>

<figure class="highlight"><pre><code class="language-json" data-lang="json"><span class="p">{</span><span class="w">
</span><span class="nl">"lua_paths"</span><span class="p">:</span><span class="w"> </span><span class="p">[</span><span class="s2">"/path/to/buildcache-wrappers/mozilla"</span><span class="p">],</span><span class="w">
</span><span class="nl">"max_cache_size"</span><span class="p">:</span><span class="w"> </span><span class="mi">10737418240</span><span class="p">,</span><span class="w">
</span><span class="nl">"max_local_entry_size"</span><span class="p">:</span><span class="w"> </span><span class="mi">2684354560</span><span class="w">
</span><span class="p">}</span></code></pre></figure>

<p>Alternatively, you can set the <code class="language-plaintext highlighter-rouge">BUILDCACHE_LUA_PATH</code> environment variable. A convenient place to do that is in your mozconfig:</p>

<figure class="highlight"><pre><code class="language-bash" data-lang="bash">mk_add_options <span class="s2">"export BUILDCACHE_LUA_PATH=/path/to/buildcache-wrappers/mozilla/"</span></code></pre></figure>

<p>The large <code class="language-plaintext highlighter-rouge">max_local_entry_size</code> (2.5 GB) is needed because some Rust crates produce very large cache entries.</p>

<h2 id="whats-next">What’s next</h2>

<p>The Lua plugin system is the interesting part here. The WebIDL wrapper is a proof of concept, but the same technique applies to any deterministic build step that takes known inputs and produces known outputs. There are other codegen actions in the Firefox build that could get the same treatment, and I plan to explore those next.</p>

<h4 id="notes">Notes</h4>

<div class="footnotes" role="doc-endnotes">
  <ol>
    <li id="fn:1">
      <p>For a clobber build with a warm cache <a href="#fnref:1" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:2">
      <p>On my machine <a href="#fnref:2" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
  </ol>
</div>

<script src="https://utteranc.es/client.js" repo="farre/blog" issue-term="og:title" label="comments" theme="github-light" crossorigin="anonymous" async="">
</script>]]></content><author><name>Andreas Farre</name></author><category term="mozilla" /><category term="mach" /><category term="buildcache" /><category term="hobby" /><summary type="html"><![CDATA[In the previous post, I mentioned that buildcache has some unique properties compared to ccache and sccache. One of them is its Lua plugin system, which lets you write custom wrappers for programs that aren’t compilers in the traditional sense. With Bug 2027655 now merged, we can use this to cache Firefox’s WebIDL binding code generation.]]></summary></entry><entry><title type="html">BuildCache now works with mach</title><link href="https://blog.farre.se/posts/2026/04/09/buildcache-with-mach/" rel="alternate" type="text/html" title="BuildCache now works with mach" /><published>2026-04-09T00:00:00+00:00</published><updated>2026-04-09T00:00:00+00:00</updated><id>https://blog.farre.se/posts/2026/04/09/buildcache-with-mach</id><content type="html" xml:base="https://blog.farre.se/posts/2026/04/09/buildcache-with-mach/"><![CDATA[<p>I’m happy to announce that <a href="https://gitlab.com/bits-n-bites/buildcache">buildcache</a> is now a first-class compiler cache in <code class="language-plaintext highlighter-rouge">mach</code>. This has been a long time coming, and I’m excited to finally see it land.</p>

<!-- more -->

<p>For those unfamiliar, <a href="https://gitlab.com/bits-n-bites/buildcache">buildcache</a> is a compiler cache that can drastically cut down your rebuild times by caching compilation results. It’s similar to ccache, but even more so sccache, in that it supports C/C++ out of the box, as well as Rust. It has some nice unique properties of its own though, which we’ll look at more closely in following posts.</p>

<h2 id="getting-started">Getting started</h2>

<p>Setting it up is straightforward. Just add the following to your mozconfig:</p>

<figure class="highlight"><pre><code class="language-bash" data-lang="bash">ac_add_options <span class="nt">--with-ccache</span><span class="o">=</span>buildcache</code></pre></figure>

<p>Then build as usual:</p>

<figure class="highlight"><pre><code class="language-bash" data-lang="bash">./mach build</code></pre></figure>

<p>That’s it.</p>

<h2 id="give-it-a-try">Give it a try</h2>

<p>If you run into any issues, please file a bug and tag me. I’d love to hear how it works out for people, and any rough edges you might hit.</p>

<script src="https://utteranc.es/client.js" repo="farre/blog" issue-term="og:title" label="comments" theme="github-light" crossorigin="anonymous" async="">
</script>]]></content><author><name>Andreas Farre</name></author><category term="mozilla" /><category term="mach" /><category term="buildcache" /><category term="hobby" /><summary type="html"><![CDATA[I’m happy to announce that buildcache is now a first-class compiler cache in mach. This has been a long time coming, and I’m excited to finally see it land.]]></summary></entry></feed>